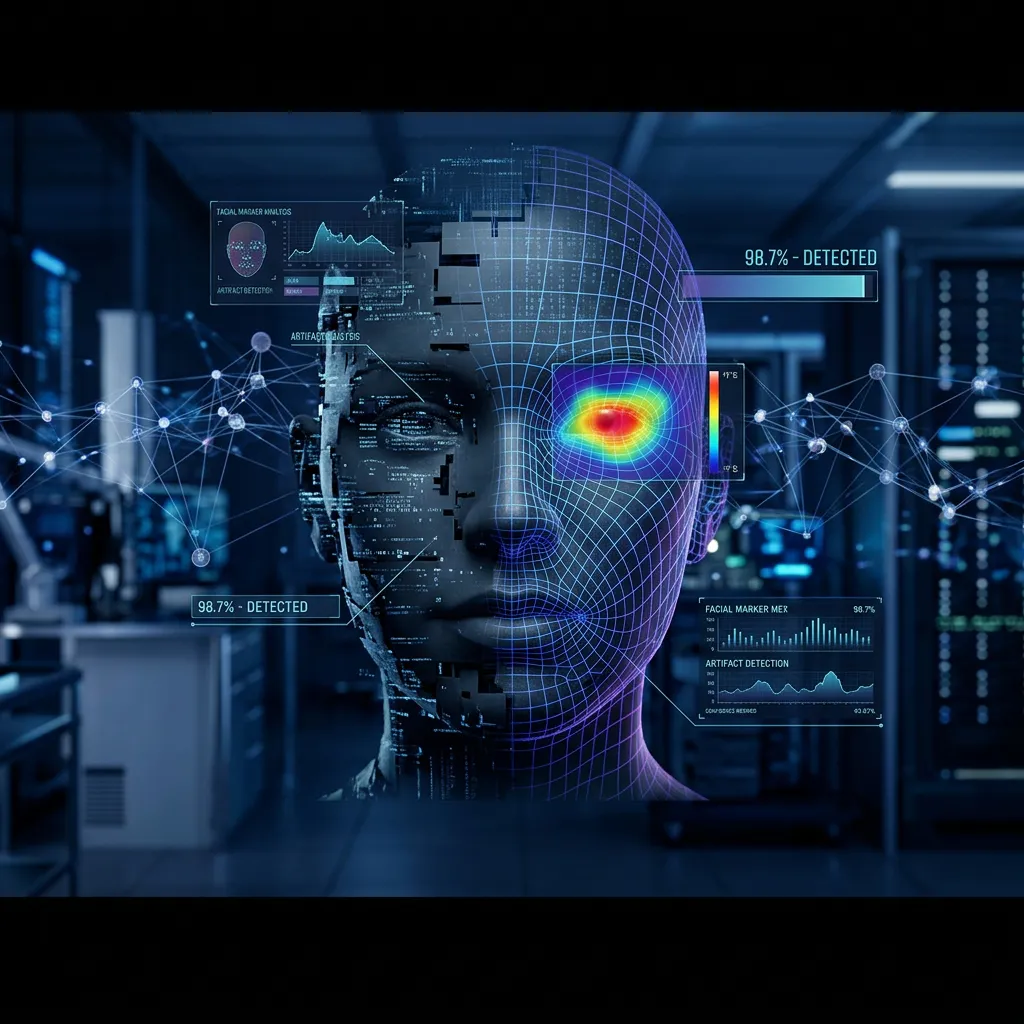
DeepShield — Digital Media Forensics & Deepfake Detection
Spatial CNN deepfake classifiers overfit to pixel-level patterns and degrade rapidly when media undergoes lossy social media compression (JPEG recompression, resizing, filtering).
My Role & Contribution
Solo Developer & ML Researcher: Engineered the multi-domain forensic feature extraction pipeline, fine-tuned the Vision Transformer model, built Grad-CAM heatmap hooks, and developed prototype FGSM adversarial immunization scripts.
Proposed Solution
Developed a forensic pipeline that decouples compression analysis from classification. Images undergo ELA and DCT frequency transformation to reveal compression inconsistencies invisible to the naked eye. These representations are fed into a fine-tuned Vision Transformer to evaluate global patch coherence. Grad-CAM visual heatmaps provide explainable diagnostic evidence.
- Combined Error Level Analysis (ELA) and DCT frequency artifacts to isolate compression tampering
- Vision Transformer (ViT-Base-16) architecture capturing global structural inconsistencies across facial patches
- Grad-CAM visual heatmap generation highlighting suspect tampered pixel clusters for explainable human review
- Dual-pass forensic verification separating spatial artifacts from compression discrepancies
- Experimental evaluation distinguishing benchmark holdout performance from real-world compressed media
Architecture & Dataflow
Implementation Status & Roadmap
Implemented
- ELA compression residual extraction script
- High-frequency DCT anomaly transform
- PyTorch ViT-Base-16 fine-tuned inference pipeline
- Grad-CAM visual attention heatmap generator
- Prototype FGSM adversarial noise immunization concept
Planned Roadmap
- Temporal multi-frame transformer for continuous video sequence analysis
- Audio-visual sync inconsistency detection for multimodal deepfakes
- Browser extension for automated client-side image forensics
Engineering Trade-offs & Limitations
Rationale:Vision Transformers have higher memory requirements and longer inference times than lightweight CNNs, but their self-attention mechanism across non-adjacent facial patches provides superior resistance to compression laundering. Decoupled Grad-CAM generation to run asynchronously to maintain API responsiveness.
Results & Evaluation
Achieved strong validation accuracy on controlled synthetic GAN holdout test sets under simulated compression. Highlighted the crucial distinction between experimental test-set accuracy and open-world reliability, emphasizing explainable Grad-CAM review over unverified single-score trust.